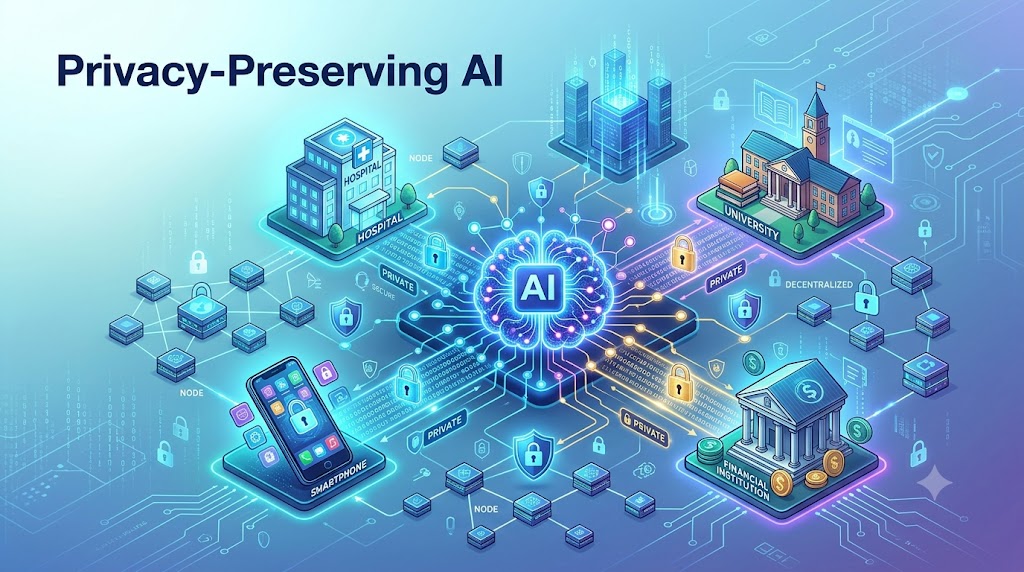
Category: Data Privacy · Federated Learning · AI Governance


Artificial intelligence (AI) is transforming healthcare, education, banking, scientific research, and everyday digital services. But many AI systems depend on large amounts of data, including information that can reveal people’s identities, habits, financial activities, educational performance, and medical histories.
This creates an important question: Can AI systems learn from personal data without directly accessing or exposing the information itself?
Privacy-preserving AI aims to make this possible. By using techniques such as federated learning, differential privacy, secure multiparty computation, and homomorphic encryption, researchers are developing ways to train and operate AI systems while reducing unnecessary exposure of sensitive information.
The goal is not simply to collect less data. It is to make useful AI possible while strengthening individual privacy, organizational security, and public trust.
What Is Privacy-Preserving AI?
Privacy-preserving AI is an approach to designing, training, and deploying artificial intelligence systems so that sensitive information is protected throughout the AI lifecycle.
In traditional machine learning, an organization may collect data from many individuals and store it in a centralized database. The AI model learns patterns from this combined dataset. Although this method can be effective, concentrating sensitive information creates potential risks involving unauthorized access, data breaches, excessive collection, and misuse.
Privacy-preserving AI seeks to reduce those risks without eliminating the benefits of machine learning.
For example, a hospital network might want to develop an AI model that identifies early signs of a disease. Each hospital has valuable patient information, but sharing complete medical records with other hospitals may create privacy, legal, and ethical concerns.
Instead, the hospitals could use a privacy-preserving learning system that allows them to contribute to a shared model while keeping patient records within their own environments.
The central idea is simple: AI should learn useful patterns from data without unnecessarily exposing the people behind that data.
The Organisation for Economic Co-operation and Development (OECD) has identified privacy-enhancing technologies as important tools for trustworthy AI collaboration, while emphasizing that their effectiveness depends on implementation and the balance between privacy, usefulness, and computational costs.
Why Does AI Need Better Privacy Protection?
AI systems can process enormous amounts of information. This capability creates opportunities for innovation, but it also introduces risks that extend beyond conventional cybersecurity.

Sensitive personal information
Health records, financial transactions, private messages, location histories, and educational records can reveal details that people do not want to disclose publicly.

Data breaches and unauthorized access
Centralized databases can become attractive targets for attackers. Strong security reduces risk, but no system is completely immune to compromise.

Information leakage from trained models
Even if raw records are never shared, a model’s parameters or responses may reveal information about its training data under certain conditions.

Limited transparency and trust
People may not know what information an AI system collects, how long it is retained, or whether it is reused for another purpose.
Researchers have documented attacks such as membership inference, model inversion, and training-data extraction. These attacks can sometimes reveal whether particular records were used for training or recover sensitive features from model behavior. The level of risk depends on the model, data, attacker capabilities, and safeguards in place.
Privacy protection therefore needs to cover more than the database. It must also consider training procedures, model updates, deployed models, user queries, and the organizations or individuals who can access them.
How Can Machines Learn Without Seeing Raw Data?
Several complementary technologies can make machine learning more privacy-conscious. Each protects information in a different way.
Federated learning: Training without centralizing raw data

Federated learning is one of the best-known approaches to privacy-preserving machine learning.
In conventional training, data from different sources may be transferred to a central location. Federated learning instead brings the training process to participating devices or organizations.
A simplified process works like this:
- A central system distributes a model. Participating devices or organizations receive an initial AI model.
- Local training takes place. Each participant trains or adjusts the model using its own data, which stays in its local environment.
- Model updates are shared. Participants send updates, such as changes to model parameters, rather than necessarily sending their original records.
- Updates are combined. A coordinating server aggregates the contributions into an improved shared model.
- The process repeats. The updated model returns to participants for another training round.
This approach can help organizations collaborate when their data cannot easily be pooled. It is relevant to mobile devices, healthcare, finance, and other settings where information is distributed across separate systems.
Example: Imagine several hospitals developing a model to detect signs of a rare disease. Each hospital trains the model on its own eligible patient records. The hospitals contribute model updates to a shared training process instead of exchanging complete patient files.
The resulting model may benefit from patterns across multiple hospitals without requiring all raw records to be stored in one central database.
However, federated learning does not automatically guarantee privacy. Model updates can sometimes reveal information about individual training examples. Additional protections, such as secure aggregation and differential privacy, may be needed.
Differential privacy: Limiting what a model can reveal
Differential privacy is a mathematical framework designed to limit how much the output of a computation reveals about any single individual’s data.
A common approach in machine learning adds carefully calibrated random noise during training or to certain statistical outputs. The objective is to make the overall result less dependent on whether one person’s record was included.
For example, a university might want to understand broad patterns in student performance without revealing the results of an individual student.
A differentially private system can produce useful aggregate statistics while limiting the influence of any one student’s record.
The strength of the guarantee depends on parameters such as the privacy budget, often represented by \(\varepsilon\), and, where applicable, \(\delta\). In general, a smaller \(\varepsilon\) indicates a stronger privacy guarantee under the same formal definition and assumptions, though it may reduce model accuracy.
Differential privacy is especially important because it offers a way to describe privacy protection mathematically rather than relying only on promises that data will remain anonymous.
NIST has discussed differential privacy as a defense against attempts to extract sensitive training information from machine learning models.
Its main challenge is balancing protection and performance. Too much noise can make a model less useful, especially when training data is limited or the prediction task is complex.
Homomorphic encryption: Computing on encrypted information

Homomorphic encryption enables computations to be performed on encrypted data without first decrypting it in the usual way.
Imagine that a healthcare provider wants an AI service to analyze sensitive information but does not want the service operator to see the underlying records.
With an appropriate homomorphic encryption scheme, the provider can encrypt the input, allow supported computations to be performed on the encrypted representation, and decrypt the resulting output using the appropriate key.
The aim is to let the computation happen while the sensitive input remains protected from the party performing it.
Potential applications include confidential medical analysis, financial risk calculations, and AI services that process private user information.
The US National Institute of Standards and Technology (NIST) identifies fully homomorphic encryption as a privacy-enhancing cryptographic technology with potential applications in AI and collaborative analysis.
The limitation is computational overhead. Encrypted calculations can require substantially more time and computing resources than ordinary operations. The practicality of homomorphic encryption therefore depends on the workload, encryption scheme, and available hardware.
Secure multiparty computation: Collaborating without revealing individual inputs
Secure multiparty computation (MPC) allows multiple parties to calculate a shared result while limiting what each participant learns about the others’ private inputs.
Consider several banks that want to identify patterns associated with fraudulent transactions. Each bank has its own customer records and may not be permitted to share those records directly.
An MPC protocol could allow the banks to calculate selected joint statistics or perform an agreed computation without giving each bank unrestricted access to the others’ raw data.
Depending on the protocol, the system may use secret sharing, cryptographic operations, or other methods to distribute computation across participants.
MPC can support collaborative analytics, risk assessment, and research involving multiple organizations. Its protection depends on the protocol’s assumptions, the number of participants that may be compromised, and how outputs are released.
It can also be expensive to run at scale, particularly for large neural networks or frequent, complex computations.
Trusted execution environments: Protecting computation in use
Another approach is to use a trusted execution environment (TEE), a hardware-supported area designed to isolate sensitive code and data from parts of the surrounding system.
A TEE can allow an AI workload to process confidential information within a protected environment, even when the broader infrastructure is operated by another party.
This is useful because data can be encrypted while stored and while transmitted, yet still need protection when a computation uses it.
TEEs aim to address that gap. However, they rely on hardware and software security assumptions, correct configuration, and protection against relevant implementation vulnerabilities and side-channel attacks.
Privacy-preserving systems may combine TEEs with federated learning, cryptographic safeguards, and independent auditing to strengthen protection. The OECD identifies trusted execution environments among the technologies that can support confidential AI collaboration.
Comparing the Main Privacy-Preserving AI Technologies
| Technology | Main privacy mechanism | Key limitation |
|---|---|---|
| Federated learning | Keeps raw training data distributed locally | Model updates may leak information |
| Differential privacy | Limits individual contributions through formal mathematical guarantees | Noise can reduce accuracy |
| Homomorphic encryption | Supports computation on encrypted data | High computational cost for many workloads |
| Secure multiparty computation | Enables joint computation while restricting access to private inputs | Communication and coordination overhead |
| Trusted execution environments | Isolates computation in a protected hardware environment | Hardware and implementation vulnerabilities |
These techniques solve different problems. Federated learning changes where training occurs; differential privacy limits information leakage; encryption-based techniques protect computations or inputs; and trusted execution environments isolate workloads.
A robust privacy-preserving AI system may combine several of these methods rather than relying on one technology alone. No single technique guarantees protection against every threat.
Real-World Applications of Privacy-Preserving AI

Healthcare and medical research
Hospitals and research institutions can explore collaborative AI training without creating a single repository of all participating patients’ records. Applications include medical imaging, disease-risk prediction, and research into uncommon conditions.
The challenge is ensuring that model updates, outputs, and access controls do not expose patient information.

Banking and financial services
Financial institutions can investigate privacy-preserving ways to detect fraud, identify suspicious transaction patterns, and assess risk across organizational boundaries.
Such systems need to protect transaction details while maintaining sufficient accuracy to detect real threats.

Mobile devices and personal assistants
On-device learning and federated approaches can help improve features such as text prediction and personalization without routinely transferring all raw user interactions to a central training system.
The overall privacy outcome still depends on implementation, telemetry, retention policies, and the handling of model updates.

Education and personalized learning
Schools and universities can explore collaborative learning analytics while limiting unnecessary disclosure of students’ academic records, learning difficulties, and individual performance.
Strong governance is essential when students are children or when data could affect educational opportunities.

Manufacturing and industrial AI
Companies may collaboratively analyze machine performance, equipment failures, and production quality without disclosing all their proprietary operational data to competitors or external service providers.
Here, privacy protection can overlap with trade-secret protection and industrial cybersecurity.
These applications are technically plausible and are supported by research into privacy-enhancing technologies. Their potential benefits should not be confused with proof that every proposed deployment has achieved reliable privacy or improved outcomes in practice.
A Recent Research Direction: Verifiable Privacy in Federated Learning
An important development in this field was reported by Google Research on October 2, 2026. The team described a federated learning system designed to provide externally verifiable privacy guarantees while shifting some computation to the server to improve training speed and device coverage. The approach uses trusted execution environments and builds on earlier work in differential privacy and secure aggregation.
Why does this matter?
Federated learning has traditionally been described in terms of keeping raw data on local devices. But researchers and system designers have increasingly recognized that keeping data local is only one part of the privacy problem.
A stronger system also needs to establish what computations can access the data, what information leaves each participant’s environment, and how privacy claims can be independently checked.
The emerging research direction emphasizes four principles:
- Data minimization: Process only the information required for the intended task.
- Data protection: Reduce the chance that identifying information can be recovered from training or outputs.
- Transparency and control: Give participants meaningful information and control over data use.
- Verifiability and auditability: Make it possible to inspect or verify important privacy protections.
This direction is promising, but a research announcement is not sufficient evidence that every privacy threat has been eliminated or that the approach is optimal for every deployment.
The broader lesson is that privacy should be demonstrable, not merely advertised.
Can Privacy-Preserving AI Protect Large Language Models?
Large language models (LLMs) introduce additional privacy challenges because they can process and generate text that resembles the material used during training.
A model may be trained on public documents, licensed content, private organizational records, or other datasets. Depending on the training process and safeguards, a model can sometimes memorize and reproduce sensitive information.
Privacy risks can arise in several ways:
Training-data extraction: An attacker may attempt to prompt a model to reproduce memorized text or sensitive details.
Membership inference: An attacker may try to determine whether a person’s information was included in a model’s training dataset.
Model inversion: Information about training examples may be inferred from a model’s behavior or outputs.
Prompt and conversation exposure: Personal information entered during use may be stored, logged, or processed by systems outside the user’s device, depending on the service’s design and policies.
A 2025 survey of privacy risks in large language models examines these kinds of attacks and reviews defenses, including federated learning and confidential computing.
Possible safeguards include:
- Removing unnecessary personal information from training datasets.
- Using differential privacy where appropriate and evaluating the resulting privacy guarantees.
- Restricting access to sensitive datasets and model outputs.
- Applying encryption and secure computation to suitable workflows.
- Limiting conversation retention and providing clear data-use controls.
- Testing models for memorization and information extraction before deployment.
However, federated learning is not automatically a complete solution for LLMs. Large models can be expensive to train across distributed devices, and local model updates can themselves contain sensitive signals. Privacy engineering must therefore be matched to the actual training and deployment architecture.
The Limitations: Why Privacy-Preserving AI Is Not Perfect
Privacy-preserving AI is a significant research area, but several challenges remain.
Privacy versus model accuracy
Differential privacy can introduce noise that reduces the usefulness of a model. The impact depends on the task, dataset size, training procedure, and strength of the privacy guarantee.
Computational complexity
Encryption and secure computation may add substantial processing and communication costs. These overheads can make some techniques impractical for real-time or large-scale workloads.
Residual privacy attacks
Keeping raw records local does not prevent all attacks. Researchers have shown that federated learning updates and trained models can reveal sensitive information under some conditions.
Unequal representation and bias
Organizations may have very different datasets, computing resources, and participation rates. A privacy-preserving system can still produce biased or unreliable results if the training data is unrepresentative.
Consent and accountability
Technical protections do not automatically establish a lawful purpose for processing information. Organizations still need appropriate permissions, governance, accountability, and ways to address complaints.
Research reviews emphasize that privacy attacks, system design, and practical trade-offs must all be considered when evaluating these technologies.
Another important distinction is between privacy and security. Security protects systems against unauthorized access and manipulation. Privacy concerns whether information is collected, used, inferred, shared, or retained appropriately. A system can be technically secure while still collecting excessive information or using it for an unexpected purpose.
Privacy-preserving AI needs to address both.
AI Governance: Who Is Responsible for Protecting Personal Data?
Privacy-preserving AI is not only a technical challenge. It is also a question of governance: who controls the data, who decides how it is used, and who is accountable when something goes wrong?
An organization cannot rely entirely on an AI vendor’s assurance that its technology is private. It needs to understand the system’s actual protections, limitations, and responsibilities.
Data protection laws and responsible AI
In India, the Digital Personal Data Protection Act, 2023, provides a statutory framework for processing digital personal data. Its application, relevant rules, commencement notifications, and obligations must be assessed according to the applicable legal provisions and dates. Organizations should consult official government sources rather than assume every requirement applies identically at every point in time.
Internationally, the European Union’s General Data Protection Regulation (GDPR) establishes requirements concerning personal-data processing, including purpose limitation, data minimization, security, and individual rights, subject to its scope and applicable exceptions.
Privacy-enhancing technologies can help organizations meet certain data-protection objectives, but using a privacy technology does not automatically make an AI system legally compliant.
Responsible AI governance should address:
- Purpose limitation: Define why personal data is needed and prevent unauthorized secondary uses.
- Data minimization: Avoid collecting information that is unnecessary for the task.
- Access controls: Restrict access to sensitive records, training systems, and model outputs.
- Risk assessments: Evaluate privacy threats before deployment and after significant system changes.
- Transparency: Explain how personal information is used in understandable language.
- Independent evaluation: Test whether privacy claims hold under realistic attack conditions.
- Accountability: Establish clear responsibility for security incidents, complaints, and corrective action.
The OECD’s work on privacy-enhancing technologies highlights the importance of combining technical safeguards with policy, governance, and practical implementation.
A practical privacy framework for AI developers
Organizations can follow a structured process when building a privacy-conscious AI system.
- Define the privacy objective. Decide whether the main concern is protecting raw data, preventing training-data extraction, hiding inputs from a service provider, or enabling collaboration between organizations.
- Choose the appropriate technology. Federated learning may suit distributed datasets, differential privacy may limit individual influence, and encryption-based methods may suit confidential computation.
- Combine safeguards where necessary. A system might use federated learning with secure aggregation and differential privacy rather than depending on local data storage alone.
- Measure the trade-offs. Evaluate prediction quality, computing cost, privacy guarantees, and performance across different groups.
- Test for privacy attacks. Assess whether attackers can infer membership, reconstruct sensitive inputs, or extract information through model queries.
- Monitor after deployment. Reassess privacy as datasets, models, software, threats, and organizational practices change.
A useful privacy assessment should document its threat model: what information needs protection, who might attack the system, what access they have, and what assumptions the safeguards rely on.
Without this information, claims such as “fully private AI” are difficult to evaluate meaningfully.
The Future of Privacy-Preserving AI

The future of privacy-preserving AI will likely involve combinations of technologies rather than one universal solution.
Federated learning could enable more organizations to collaborate on machine learning. Differential privacy could provide measurable limits on the influence of individual records. Cryptographic techniques could support confidential computation, while trusted execution environments could isolate sensitive workloads.
Researchers are also investigating ways to make these protections easier to verify and more efficient to deploy. Developments in hardware, cryptography, and distributed computing may gradually make privacy-enhancing methods practical for a wider range of AI applications.
Several research questions remain particularly important:
Can privacy be improved without sacrificing useful accuracy? Researchers need better ways to measure the relationship between privacy guarantees and model performance, particularly for smaller datasets and specialized tasks.
Can AI models be audited for information leakage? Testing methods must keep pace with increasingly capable models and attacks.
Can smaller organizations adopt these technologies affordably? Healthcare providers, universities, and smaller businesses may lack the computing resources or specialist expertise required for advanced cryptographic methods.
Can privacy and fairness be improved together? A system must protect individual information while ensuring that its predictions do not systematically disadvantage particular populations.
Can users verify what happens to their data? Stronger transparency and independent verification could help move privacy from a marketing promise to an accountable engineering property.
These questions will shape the next generation of privacy-preserving machine learning.
Conclusion
Privacy-preserving AI offers a promising answer to one of the most important questions in modern technology: can machines learn from data without unnecessarily exposing personal information?
Federated learning allows models to learn across distributed datasets without routinely centralizing raw records. Differential privacy offers formal guarantees that limit individual contributions. Homomorphic encryption and secure multiparty computation can support confidential analysis, while trusted execution environments protect selected computations.
Each method has limitations, and none eliminates every privacy risk. Successful deployment requires careful engineering, realistic security testing, responsible data governance, and transparency about what a system can and cannot guarantee.
The goal is not to make AI independent of all data. It is to make AI more selective, accountable, and respectful in how it uses information.
Ultimately, the future of trustworthy AI will depend not only on how intelligently machines learn, but also on how effectively they protect the people who make that learning possible.